Evaluations are structured runs that measure agent quality by comparing agent outputs against the expected outputs in a dataset. They produce metric scores that let you track quality over time, validate the effect of configuration changes, and catch regressions before they reach production.
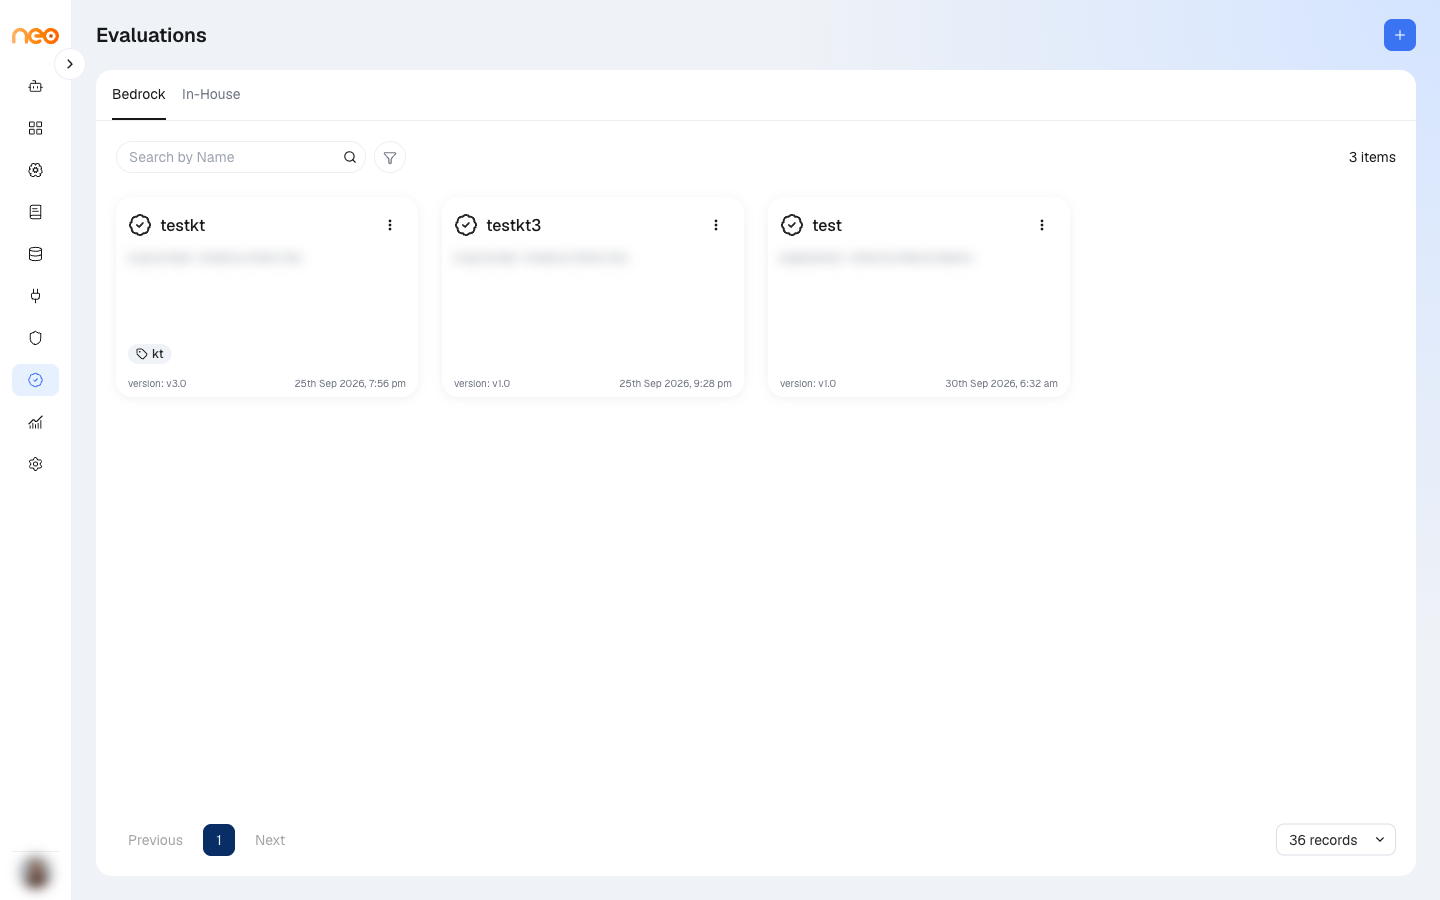
OneByZero Neo supports two evaluation frameworks, accessible from tabs on the Evaluations page:
- In-House (DeepEval) — evaluations powered by DeepEval, an open-source framework with a rich set of metrics for assessing LLM outputs. Each evaluation run processes the dataset items and computes metrics such as answer relevancy, hallucination, faithfulness, toxicity, and bias.
- Bedrock — integration with AWS Bedrock Evaluations. Supports programmatic evaluation (deterministic, algorithm-based metrics) and model-as-a-judge evaluation (an LLM judges response quality against metrics such as correctness, helpfulness, and coherence).
Both frameworks use the Datasets you have built in the Foundry. An evaluation references a dataset and runs each item through the configured metrics to produce scores.
Managing evaluations
Both evaluation types support:
- Search — find evaluations by name.
- Tagging — organise evaluations by project, agent, or purpose.
- Versioning — evaluations display their current version. New versions can be created as your configuration evolves.
- Runs history — each evaluation maintains a history of execution runs, allowing you to compare scores across runs and track improvement over time.
In this section: