This guide covers deploying OneByZero Neo on enterprise AWS accounts using Terraform and Helm for infrastructure provisioning and application deployment.
Overview
OneByZero Neo is a modular AI platform supporting Chatbot, Voice Bot, and Agentic Flow agents. The system runs in a multi-zone Amazon EKS cluster for high availability and uses GitOps (ArgoCD) for continuous deployment.
The platform integrates with:
- Amazon RDS PostgreSQL - Primary relational database
- Amazon OpenSearch - Vector storage and semantic search
- ClickHouse - Time-series analytics database
- Amazon S3 - Object storage for documents and models
Infrastructure as a Service Deployment
OneByZero Neo follows an Infrastructure as a Service (IaaS) deployment model on AWS, where the complete platform is deployed within the enterprise’s own AWS account. This approach provides:
Data Sovereignty : All data remains within the enterprise’s AWS account and VPC. No data is transmitted to external systems, ensuring compliance with data residency requirements.
Network Isolation : The platform operates within private subnets with configurable security groups and network ACLs. External access is controlled through AWS Application Load Balancer with SSL termination.
IAM Integration : Services authenticate to AWS resources using IAM Roles for Service Accounts (IRSA), eliminating the need for long-lived credentials.
Resource Control : Enterprises maintain full control over compute resources, scaling policies, and cost management through AWS native tools.
Deployment Architecture
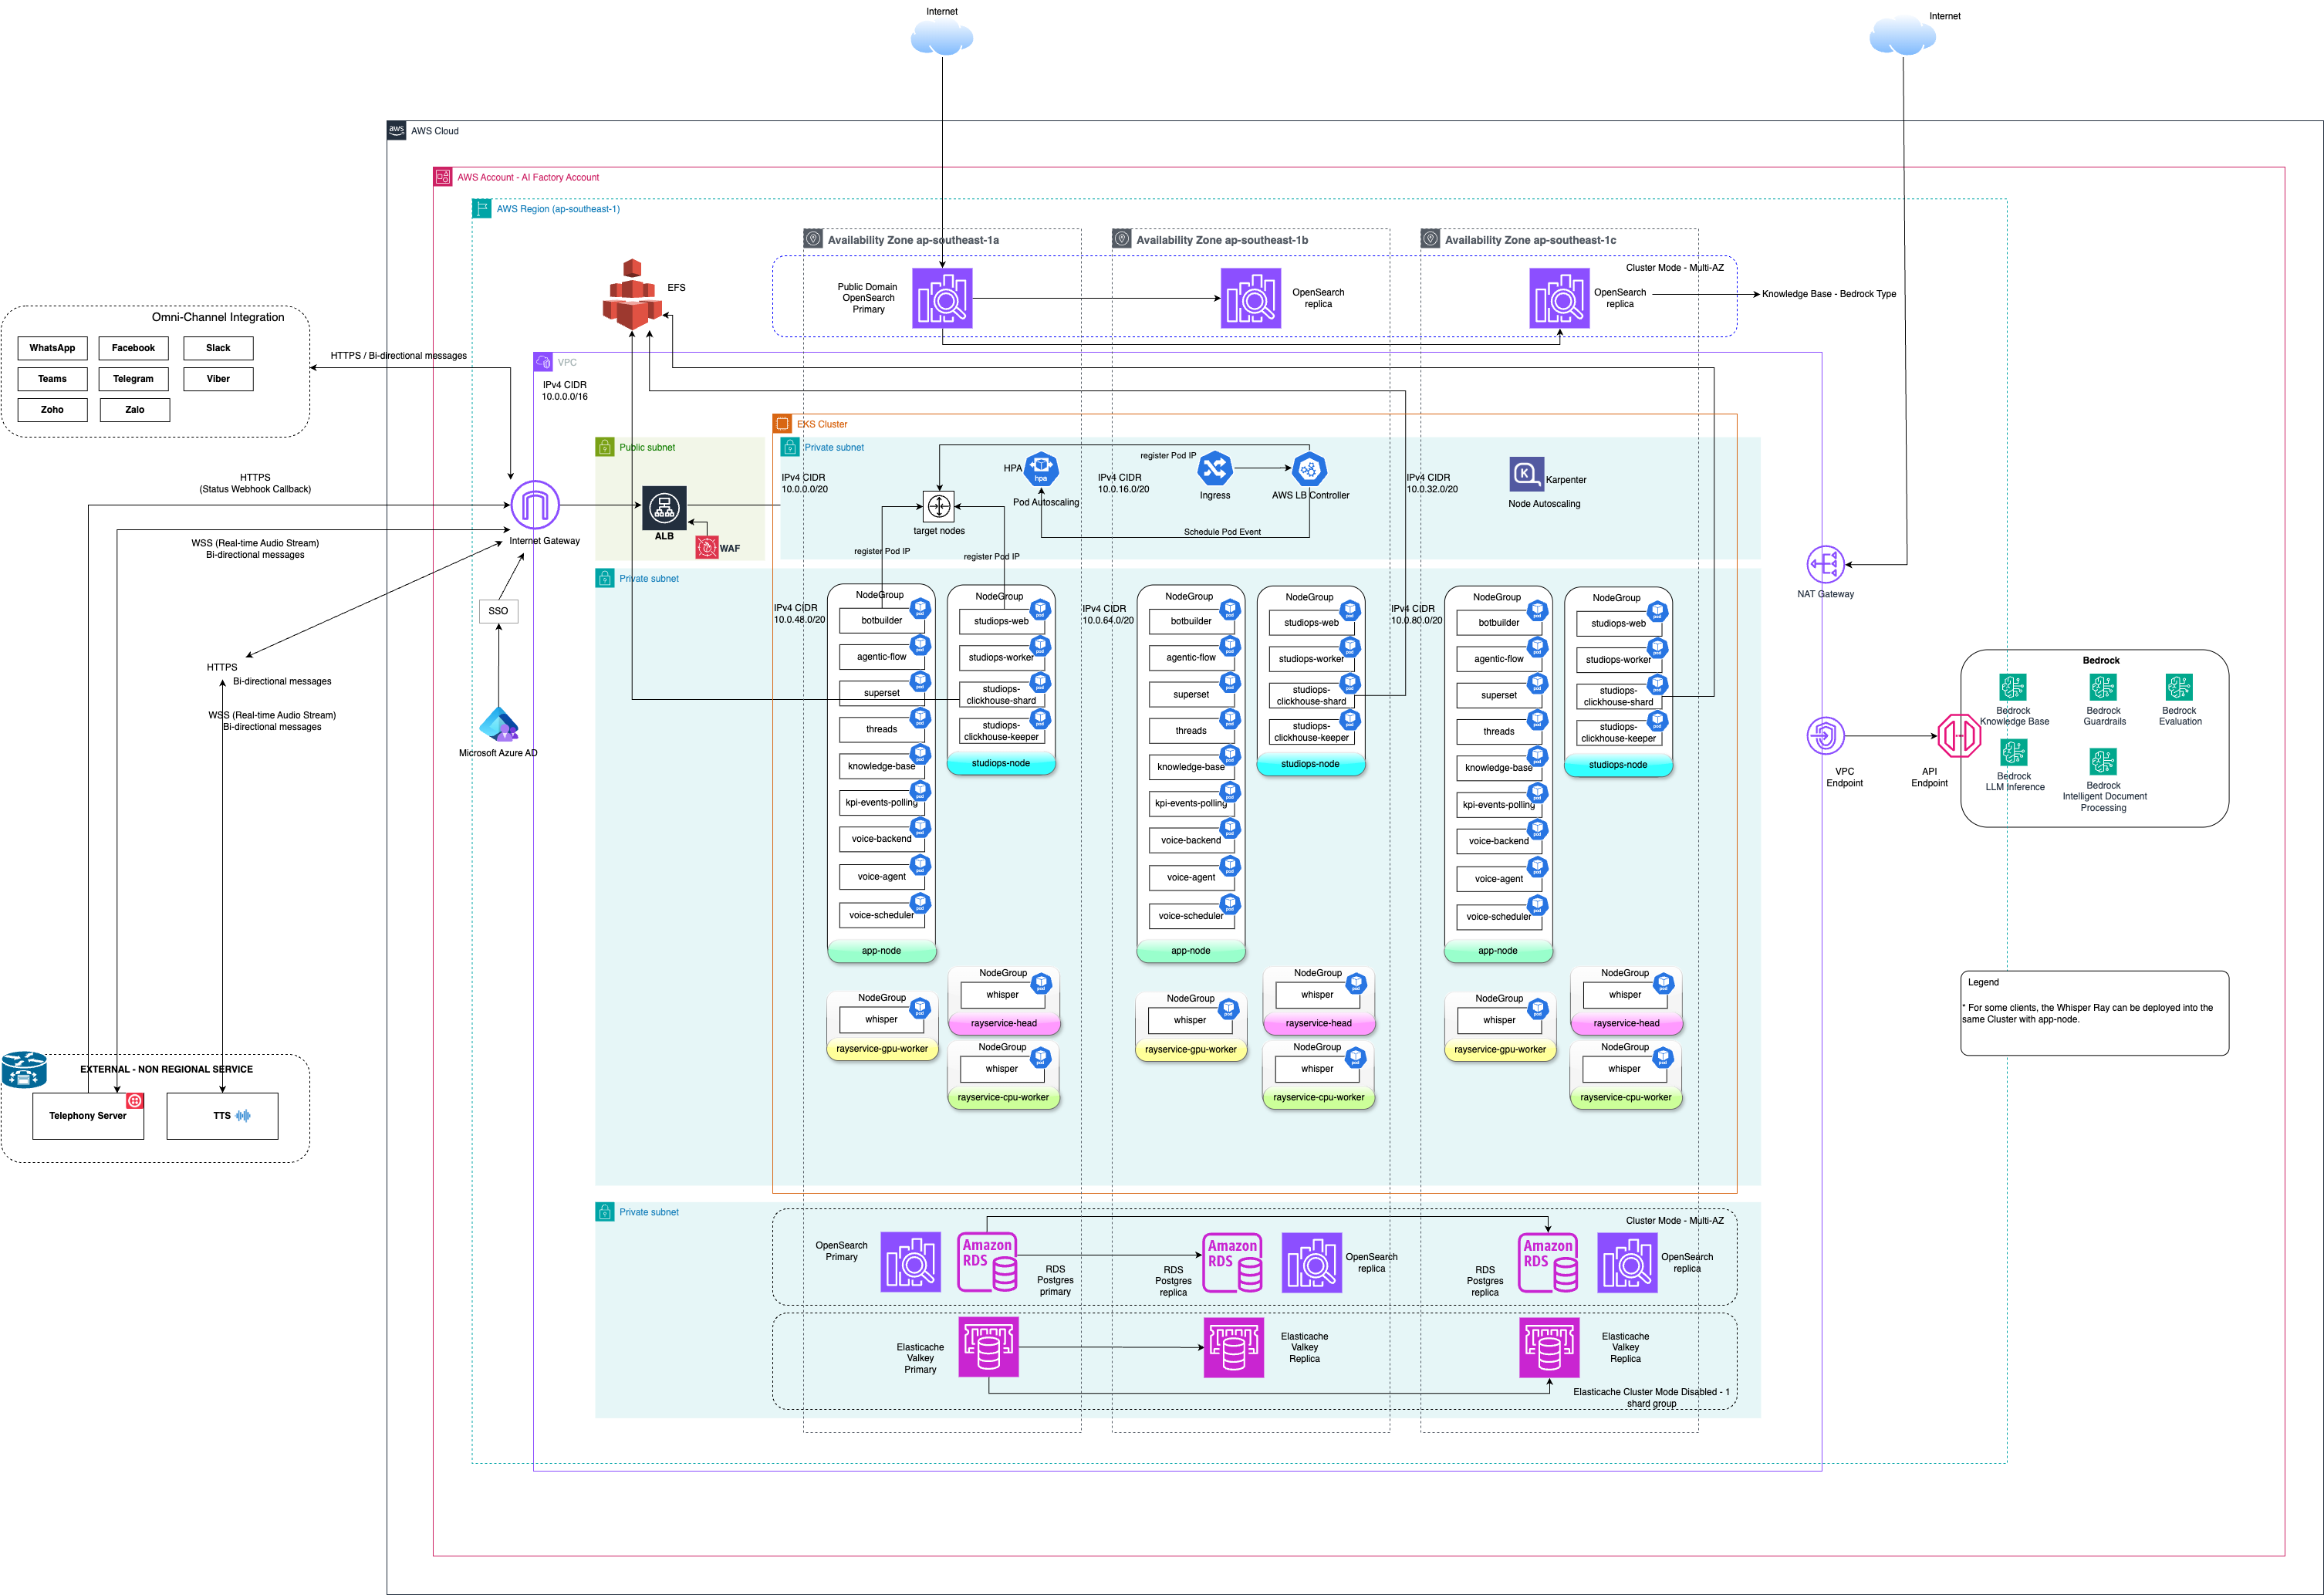
OneByZero Neo deployment architecture showing the Enterprise AWS Account with VPC, EKS cluster node pools, and AWS managed services.
Prerequisites
Infrastructure Requirements
-
Amazon EKS cluster (v1.24+)
-
Node groups with appropriate taints and labels:
app-nodepool for application workloadsstudiops-nodepool for Langfuse/ClickHouse
-
AWS Application Load Balancer Controller
-
External DNS Controller
-
Amazon RDS PostgreSQL instance
-
Amazon OpenSearch cluster
-
AWS S3 buckets for data storage
-
AWS SQS queues for message processing
Required AWS Resources
RDS Database : PostgreSQL instance for application data persistence.
OpenSearch Domain : Managed OpenSearch cluster for vector storage and semantic search.
S3 Buckets
- Data ingestion bucket
- StudioOps bucket
- StudioOps datasets bucket
- Bedrock knowledge base data ingestion bucket
- Supplemental storage bucket
- Voice schedule bucket
- Bedrock evaluators bucket
SQS Queues
- KPI events queue
- Voice calls queue
Security Requirements
- IAM Role for EKS IRSA (IAM Roles for Service Accounts)
- SSL Certificate from AWS Certificate Manager (ACM)
- Application Load Balancer for ingress traffic
Password Generation Guidelines
Database passwords (RDS PostgreSQL, Redis, ClickHouse) should use URL-safe characters to prevent connection string parsing issues.
Safe Characters (No Encoding Required)
A-Z a-z 0-9 _ - . ~
Characters to Avoid
@ : / ? # & = % + (space) ; " ' < > \ ^ ` { } [ ]
If special characters must be used, URL-encode the password before storing:
python3 -c "import urllib.parse; print(urllib.parse.quote_plus('your-password'))"
Keys Generation
Generate required encryption keys and secrets before deployment:
| Service | Variable | Generation Command |
|---|---|---|
| Langfuse | SALT | openssl rand -base64 32 |
| Langfuse | ENCRYPTION_KEY | openssl rand -hex 32 |
| Langfuse | LANGFUSE_KEY | openssl rand -base64 32 |
| Langfuse | NEXTAUTH_SECRET | openssl rand -base64 32 |
| Agentic Flow | DEFAULT_SUPERUSER_PASSWORD | openssl rand -base64 32 |
| Agentic Flow | LANGFLOW_SECRET_KEY | openssl rand -base64 32 |
| Bot Builder | ENCRYPTION_SECRET | openssl rand -base64 24 |
| Bot Builder | JWT_SIGNING_KEY_ID | openssl rand -base64 24 |
| Knowledge Base | PE_PASSPHRASE | openssl rand -base64 43 |
JWT Key Pair Generation
# Generate private key
openssl genpkey -algorithm RSA -out private_key.pem

# Generate public key from private key
openssl rsa -pubout -in private_key.pem -out public_key.pem
Helm Deployment Process
Pre-deployment Validation
# Verify cluster connectivity
kubectl cluster-info

# Check node readiness
kubectl get nodes

# Verify required namespaces
kubectl create namespace <NAMESPACE> --dry-run=client -o yaml | kubectl apply -f -

# Validate AWS Load Balancer Controller
kubectl get deployment -n kube-system aws-load-balancer-controller
Deploy Infrastructure Services
Deploy infrastructure services first as they are dependencies for application services.
Voice Redis
helm upgrade --install voice-redis ./voice_redis \
  --namespace <NAMESPACE> \
  --create-namespace \
  --wait \
  --timeout 10m
Langfuse (StudioOps)
helm upgrade --install langfuse ./langfuse \
  --namespace <NAMESPACE> \
  --wait \
  --timeout 15m
Hulaho (Analytics Dashboard)
helm upgrade --install hulaho ./hulaho \
  --namespace <NAMESPACE> \
  --wait \
  --timeout 15m
Deploy Core Application Services
Deploy services in dependency order:
# EKS Jobs Managing Service (required by Knowledge Base)
helm upgrade --install eks-jobs-managing ./eks_jobs_managing_service \
  --namespace <NAMESPACE> \
  --wait \
  --timeout 10m

# Knowledge Base Service
helm upgrade --install knowledge-base ./knowledge_base \
  --namespace <NAMESPACE> \
  --wait \
  --timeout 10m

# Agentic Flow Service
helm upgrade --install agentic-flow ./agentic_flow \
  --namespace <NAMESPACE> \
  --wait \
  --timeout 10m

# Bot Builder Services
helm upgrade --install botbuilder ./botbuilder \
  --namespace <NAMESPACE> \
  --wait \
  --timeout 10m

# KPI Events Polling Service
helm upgrade --install kpi-events-polling ./kpi_events_polling_service \
  --namespace <NAMESPACE> \
  --wait \
  --timeout 10m

# Threads Service
helm upgrade --install threads-service ./threads_service \
  --namespace <NAMESPACE> \
  --wait \
  --timeout 10m
Deploy Voice Services
# Voice Backend
helm upgrade --install voice-backend ./voice_backend \
  --namespace <NAMESPACE> \
  --wait \
  --timeout 10m

# Voice Agent
helm upgrade --install voice-agent ./voice_agent \
  --namespace <NAMESPACE> \
  --wait \
  --timeout 10m

# Voice Scheduler
helm upgrade --install voice-scheduler ./voice_scheduler \
  --namespace <NAMESPACE> \
  --wait \
  --timeout 10m
Verification
# Check all deployments
kubectl get deployments -n <NAMESPACE>

# Check all services
kubectl get services -n <NAMESPACE>

# Check ingress resources
kubectl get ingress -n <NAMESPACE>

# Check pod status
kubectl get pods -n <NAMESPACE>

# View logs for troubleshooting
kubectl logs -f deployment/<service-name> -n <NAMESPACE>
Upgrade and Rollback
Upgrade Process
helm upgrade <release-name> ./<chart-directory> \
  --namespace <NAMESPACE> \
  --reuse-values \
  --wait \
  --timeout 10m
Rollback Process
# List release history
helm history <release-name> --namespace <NAMESPACE>

# Rollback to previous version
helm rollback <release-name> --namespace <NAMESPACE>

# Rollback to specific revision
helm rollback <release-name> <revision-number> --namespace <NAMESPACE>
Service Configuration Reference
This section documents all required environment variables for each microservice. Variables not listed are considered optional and use default values.
Note
All secrets should be stored in HashiCorp Vault or Kubernetes Secrets and mapped to deployments using the VaultStaticSecrets CRD or native Kubernetes secret references.
Agentic Flow Service
AI workflow orchestration and LangFlow integration service that manages AI workflows and provides API endpoints for conversational AI applications.
Network & Application Configuration
| Variable | Description |
|---|---|
| ADDITIONAL_CORS_ORIGINS | Comma-separated list of allowed CORS origin domains |
| HOST | Application bind address for container networking |
| APPLICATION_PORT | Port number for the application server |
Database Configuration
| Variable | Description |
|---|---|
| LANGFLOW_DATABASE_URL | PostgreSQL connection string for workflow persistence |
| LANGFLOW_SCHEMA_NAMES | Database schemas used by LangFlow for multi-tenant data organization |
Logging & Monitoring
| Variable | Description |
|---|---|
| LANGFLOW_LOG_LEVEL | Application logging verbosity level |
| STUDIOTELEMETRY_COLLECTOR_ENDPOINT | OpenTelemetry metrics collection endpoint |
| STUDIOTELEMETRY_COLLECTOR_AUTH_TOKEN | Authentication token for telemetry data submission |
API Integration
| Variable | Description |
|---|---|
| GUARDRAIL_API_BASE_URL | API endpoint for content guardrails and safety checks |
Feature Flags
| Variable | Description |
|---|---|
| SHOULD_ALLOW_CUSTOM_COMPONENT_CREATION | Allows builders to create and edit custom component code in the flow editor. Default: false — requests to save custom component code are refused |
OpenSearch Configuration
| Variable | Description |
|---|---|
| INHOUSE_OPENSEARCH_HOST | OpenSearch cluster endpoint for vector storage |
| INHOUSE_OPENSEARCH_USERNAME | OpenSearch authentication username |
| INHOUSE_OPENSEARCH_PASSWORD | OpenSearch authentication password |
AWS Bedrock Knowledge Base Configuration
| Variable | Description |
|---|---|
| BEDROCK_KNOWLEDGE_BASE_OPENSEARCH_HOST | Bedrock knowledge base OpenSearch endpoint |
| BEDROCK_KNOWLEDGE_BASE_OPENSEARCH_USERNAME | Bedrock knowledge base OpenSearch username |
| BEDROCK_KNOWLEDGE_BASE_OPENSEARCH_PASSWORD | Bedrock knowledge base OpenSearch password |
Resource Requirements
- CPU: 1000m (requests) / 1290m (limits)
- Memory: 1Gi (requests) / 2Gi (limits)
Node Placement
- Node Selector:
node-pool: app-node - Tolerations:
workload=app:NoSchedule
Health Check: /health_check
Dependencies: PostgreSQL, OpenSearch, AWS Bedrock, StudioOps telemetry service
Bot Builder Service
Conversational bot creation and management platform with separate builder and viewer components for designing and running chatbots.
Builder Component - Application Configuration
| Variable | Description |
|---|---|
| APPLICATION_HOSTNAME | Application bind address |
| APPLICATION_PORT | Application server port |
| BASE_URL_FROM_ENV | Base URL for the builder application |
Authentication & Security
| Variable | Description |
|---|---|
| AZURE_AD_CLIENT_ID | Azure Active Directory application client ID |
| AZURE_AD_CLIENT_SECRET | Azure AD application secret |
| AZURE_AD_TENANT_ID | Azure AD tenant identifier |
| NEXTAUTH_URL | NextAuth authentication service URL |
| JWT_SIGNING_KEY_ID | JWT token signing key identifier |
| JWT_EXPIRATION_IN_HOURS | JWT token expiration time in hours |
| ENCRYPTION_SECRET | Data encryption secret key |
| JWT_PRIVATE_KEY_PATH | Path to JWT private key PEM file (mounted from secrets) |
| JWT_PUBLIC_KEY_PATH | Path to JWT public key PEM file (mounted from secrets) |
Database Configuration
| Variable | Description |
|---|---|
| DATABASE_URL | PostgreSQL connection string for bot configurations |
Bot Behavior Configuration
| Variable | Description |
|---|---|
| BUILDER_ALLOWED_ORIGINS | CORS allowed origins for development |
| BUTTON_CHOICE_INTERRUPTION | Enable button choice interruption in conversations |
| FILE_INPUT_INTERRUPTION | Enable file input interruption handling |
| PICTURE_CHOICE_INTERRUPTION | Enable picture choice interruption handling |
| CHAT_HISTORY_LIMIT | Maximum number of chat history entries to retain |
External Service Integration
| Variable | Description |
|---|---|
| NEXT_PUBLIC_GOOGLE_API_KEY | Google Maps/Services API key |
Organization & User Management
| Variable | Description |
|---|---|
| ORGANIZATION_SETUP_AUTH_TOKEN | Organization setup authentication token (must match LANGFUSE_KEY) |
| ORGANIZATION_SETUP_EMAIL | Default organization setup email |
| DEFAULT_WORKSPACE_PLAN | Default workspace plan for new users |
| ADMIN_EMAIL | System administrator email address |
| SEED_DATA | Whether to seed initial data on startup |
Session Management
| Variable | Description |
|---|---|
| NEXT_PUBLIC_SESSION_EXPIRY_TIMEOUT_IN_HOURS | Session timeout in hours for security |
Metrics & Analytics
| Variable | Description |
|---|---|
| METRICS_API_URL | Metrics collection API endpoint |
| METRICS_API_AUTH_TOKEN | Authentication token for metrics API |
| HULAHO_API_BASE_URL | Hulaho (Superset) analytics endpoint |
| HULAHO_ADMIN_PASSWORD | Hulaho user authentication password |
AWS S3 Configuration
| Variable | Description |
|---|---|
| S3_ENDPOINT | S3 service endpoint |
| S3_BUCKET | Primary S3 bucket for file storage |
| S3_REGION | AWS region for S3 operations |
| IS_IRSA_REQUIRED | Enable IAM Roles for Service Accounts |
| DATASET_S3_BUCKET | S3 bucket for dataset storage |
| DATASET_S3_REGION | AWS region for dataset bucket |
| DATASET_S3_FORCE_PATH_STYLE | Force path-style S3 URLs |
Service Integration URLs
| Variable | Description |
|---|---|
| NEXT_PUBLIC_VIEWER_URL | Bot viewer application URL |
| NEXT_PUBLIC_VOICE_AGENT_BACKEND_SERVICE_BASE_URL | Voice backend service URL |
| NEXT_PUBLIC_VOICE_AGENT_BACKEND_WS_URL | Voice backend WebSocket URL |
| NEXT_PUBLIC_AGENTIC_FLOW_URL | Agentic flow service URL |
| NEXT_PUBLIC_KNOWLEDGE_BASE_URL | Knowledge base service URL |
| NEXT_PUBLIC_DATASET_BASE_URL | Dataset management URL |
| CHANNEL_EVENT_GATEWAY_PUBLIC_URL | Public base URL of the Channel Event Gateway (e.g. https://gateway.example.com). Used to build the webhook URLs shown when you create channels for Agentic Flow agents and Coworkers. If unset, no webhook URL is shown |
Analytics Dashboard Integration
| Variable | Description |
|---|---|
| NEXT_PUBLIC_HULAHO_BASE_URL | Analytics dashboard base URL |
| NEXT_PUBLIC_HULAHO_VOICE_DASHBOARD_ID | Voice analytics dashboard identifier |
| NEXT_PUBLIC_HULAHO_CHAT_DASHBOARD_ID | Chat analytics dashboard identifier |
| NEXT_PUBLIC_HULAHO_FLOW_DASHBOARD_ID | Flow analytics dashboard identifier |
Feature Flags
| Variable | Description |
|---|---|
| NEXT_PUBLIC_IS_VOICE_FEATURE_ENABLED | Enable voice bot features |
| NEXT_PUBLIC_IS_CHAT_FEATURE_ENABLED | Enable chat bot features |
| NEXT_PUBLIC_IS_FLOW_FEATURE_ENABLED | Enable flow-based bot features |
| NEXT_PUBLIC_DEMO_MODE | Enable demo mode features |
| FF_GUARDRAIL_MODE | Guardrail mode: proxy (default) or direct. NeMo guardrails require direct |
| FF_NEMO_GUARDRAILS_ENABLED | Enables NeMo guardrails on the server. Default: false |
| NEXT_PUBLIC_FF_NEMO_GUARDRAILS_ENABLED | Shows the NeMo tab on the Guardrails page. Default: false |
Webhook Configuration
| Variable | Description |
|---|---|
| WEBHOOK_TASK_EXPIRATION_MINUTES | Webhook task timeout in minutes |
Branding
| Variable | Description |
|---|---|
| NEXT_PUBLIC_COPYWRITE_NAME | Copyright notice text |
| NEXT_PUBLIC_AWS_MODEL_REGION | AWS region for AI model access |
Viewer Component - Additional Configuration
| Variable | Description |
|---|---|
| AWS_SQS_QUEUE_URL | SQS queue URL for KPI events |
| AWS_SQS_QUEUE_REGION | AWS region for SQS operations |
| LLM_HOST_URLS | Large Language Model service endpoints |
| DATASET_S3_ENDPOINT | S3 endpoint for dataset operations |
Resource Requirements (Viewer)
- CPU: 1200m (requests) / 1290m (limits)
- Memory: 1Gi (requests) / 2Gi (limits)
Autoscaling (Viewer)
- Min Replicas: 1
- Max Replicas: 2
- Target CPU Utilization: 80%
Node Placement
- Node Selector:
node-pool: app-node - Tolerations:
workload=app:NoSchedule
Dependencies: PostgreSQL, S3, Azure AD, Voice services, Agentic Flow, Knowledge Base
Channel Event Gateway Service
Receives incoming webhook requests from channels and passes them to the right agent.
Google Chat
| Variable | Description |
|---|---|
| GOOGLE_CHAT_PROJECT_NUMBER | Google Cloud project number of the Google Chat app. Incoming Google Chat requests are accepted only when their token matches this number; if unset, every Google Chat message is rejected |
| GOOGLE_CHAT_API_BASE_URL | Base URL of the Google Chat API used to send replies. Default: https://chat.googleapis.com |
Knowledge Base Service
Document ingestion, processing, and retrieval service that manages knowledge bases, handles document uploads, and provides semantic search capabilities.
Application Configuration
| Variable | Description |
|---|---|
| APPLICATION_NAME | Service identifier for logging and monitoring |
| PORT | Application server port |
| PE_PASSPHRASE | Private encryption passphrase for sensitive data |
Database Configuration
| Variable | Description |
|---|---|
| DATABASE_URL | PostgreSQL connection string for metadata storage |
Service Integration
| Variable | Description |
|---|---|
| EKS_JOBS_MANAGING_SERVICE_BASE_URL | EKS job orchestration service endpoint |
AWS Configuration
| Variable | Description |
|---|---|
| REGION_NAME | Primary AWS region for all operations |
| DATA_INGESTION_ROLE_ARN | IAM role ARN for data ingestion operations |
S3 Storage Configuration
| Variable | Description |
|---|---|
| SOURCE_FILES_S3_BUCKET_NAME | S3 bucket for source document storage |
| SOURCE_FILES_S3_BUCKET_REGION | AWS region for source files bucket |
| MARKDOWN_FILES_S3_BUCKET_NAME | S3 bucket for processed markdown files |
| MARKDOWN_FILES_S3_BUCKET_REGION | AWS region for markdown files bucket |
OpenSearch Configuration
| Variable | Description |
|---|---|
| OPENSEARCH_HOST | OpenSearch cluster endpoint for vector storage |
| OPENSEARCH_USERNAME | OpenSearch authentication username |
| OPENSEARCH_PASSWORD | OpenSearch authentication password |
| OPENSEARCH_DOMAIN_ARN | OpenSearch domain ARN |
| OPENSEARCH_AWS_REGION | AWS region for OpenSearch operations |
Embedding Model Configuration
| Variable | Description |
|---|---|
| EMBEDDING_MODEL_AWS_REGION | AWS region for embedding model |
| EMBEDDING_MODEL_ID | AWS Bedrock embedding model identifier |
Data Ingestion Service Configuration
| Variable | Description |
|---|---|
| DATA_INGESTION_APPLICATION_NAME | Data ingestion service identifier |
| DATA_INGESTION_S3_BUCKET_NAME | S3 bucket for ingestion pipeline |
| DATA_INGESTION_JOB_CONTAINER_NAME | Kubernetes job container name |
| DATA_INGESTION_JOB_NAMESPACE | Kubernetes namespace for ingestion jobs |
| DATA_INGESTION_JOB_COMMAND | Job execution command |
| DATA_INGESTION_JOB_ECR_IMAGE_URI | Container image URI for ingestion jobs |
AI Model Configuration
| Variable | Description |
|---|---|
| DATA_INGESTION_ANTHROPIC_API_KEY | Anthropic Claude API key (if using Anthropic directly) |
AWS Bedrock Configuration
| Variable | Description |
|---|---|
| DATA_INGESTION_AWS_BEDROCK_REGION_NAME | AWS region for Bedrock operations |
| DATA_INGESTION_AWS_BEDROCK_MODEL_NAME | Bedrock model identifier |
| DATA_INGESTION_AWS_BEDROCK_MODEL_MAX_TOKENS | Maximum tokens per request |
| DATA_INGESTION_AWS_BEDROCK_MODEL_TEMPERATURE | Model temperature for response variability |
| DATA_INGESTION_AWS_BEDROCK_MODEL_TOP_P | Top-p sampling parameter |
| DATA_INGESTION_AWS_BEDROCK_MODEL_TOP_K | Top-k sampling parameter |
Bedrock Knowledge Base Configuration
| Variable | Description |
|---|---|
| BEDROCK_KNOWLEDGE_BASE_ROLE_ARN | IAM role for Bedrock knowledge base access |
| BEDROCK_KNOWLEDGE_BASE_REGION | AWS region for Bedrock knowledge base |
| BEDROCK_KNOWLEDGE_BASE_EMBEDDING_MODEL_ARN | Embedding model ARN |
| BEDROCK_KNOWLEDGE_BASE_PARSING_MODEL_ARN | Document parsing model ARN |
| BEDROCK_KNOWLEDGE_BASE_SUPPLEMENTAL_S3_URI | Supplemental storage S3 URI |
| BEDROCK_KNOWLEDGE_BASE_DATA_SOURCE_S3_ARN | Data source S3 bucket ARN |
| BEDROCK_KNOWLEDGE_BASE_DATA_SOURCE_S3_OWNER_ACCOUNT_ID | AWS account ID for S3 bucket ownership |
| BEDROCK_KNOWLEDGE_BASE_DATA_SOURCE_S3_BUCKET_NAME | S3 bucket for Bedrock data source |
| BEDROCK_KNOWLEDGE_BASE_DATA_SOURCE_S3_BUCKET_REGION | AWS region for Bedrock data source bucket |
Bedrock Knowledge Base OpenSearch Configuration
| Variable | Description |
|---|---|
| BEDROCK_KNOWLEDGE_BASE_OPENSEARCH_HOST | OpenSearch endpoint for Bedrock KB |
| BEDROCK_KNOWLEDGE_BASE_OPENSEARCH_DOMAIN_ARN | OpenSearch domain ARN for Bedrock KB |
| BEDROCK_KNOWLEDGE_BASE_OPENSEARCH_USERNAME | OpenSearch username for Bedrock KB |
| BEDROCK_KNOWLEDGE_BASE_OPENSEARCH_PASSWORD | OpenSearch password for Bedrock KB |
Resource Requirements
- CPU: 1200m (requests) / 1290m (limits)
- Memory: 1Gi (requests) / 2Gi (limits)
Node Placement
- Node Selector:
node-pool: app-node - Tolerations:
workload=app:NoSchedule
Health Check: /api/v1/health
Dependencies: OpenSearch, S3, AWS Bedrock, EKS Jobs Managing Service, PostgreSQL
Voice Agent Service
Real-time voice conversation handling service that manages voice calls, integrates with speech services, and provides conversational AI capabilities.
Agent Configuration
| Variable | Description |
|---|---|
| AGENT_NAME | AI agent implementation type |
| APPLICATION_NAME | Service identifier for logging and monitoring |
| BASE_URL | Base URL for the voice agent service |
Database Configuration
| Variable | Description |
|---|---|
| DATABASE_URL | PostgreSQL connection string for conversation persistence |
AWS Integration
| Variable | Description |
|---|---|
| AWS_SQS_QUEUE_URL | SQS queue URL for KPI events and analytics |
| AWS_REGION_NAME | AWS region for all AWS service operations |
Azure OpenAI Configuration
| Variable | Description |
|---|---|
| AZURE_OPENAI_API_KEY | Azure OpenAI service API key |
| AZURE_OPENAI_API_VERSION | Azure OpenAI API version |
| AZURE_OPENAI_DEPLOYMENT | Azure OpenAI deployment name |
| AZURE_OPENAI_ENDPOINT | Azure OpenAI service endpoint |
| AZURE_OPENAI_MODEL_NAME | Azure OpenAI model identifier |
Azure Speech Services Configuration
| Variable | Description |
|---|---|
| AZURE_SPEECH_KEY | Azure Speech Services API key |
| AZURE_SPEECH_REGION | Azure Speech Services region |
| AZURE_CANDIDATE_LANGUAGES | Supported languages for speech recognition (comma-separated) |
ElevenLabs Voice Synthesis Configuration
| Variable | Description |
|---|---|
| ELEVENLABS_API_KEY | ElevenLabs API key for voice synthesis |
| ELEVENLABS_EXPERIMENTAL_STREAMING | Enable experimental streaming features |
| ELEVENLABS_EXPERIMENTAL_WEBSOCKET | Enable WebSocket-based streaming |
| ELEVENLABS_MODEL_ID | ElevenLabs voice model identifier |
| ELEVENLABS_OPTIMIZE_STREAMING_LATENCY | Latency optimization level (1-4) |
| ELEVENLABS_VOICE_ID | Specific voice ID for synthesis |
| ELEVENLABS_VOICE_SPEED | Voice playback speed multiplier |
| ELEVENLABS_VOICE_STYLE | Voice style variation parameter |
Twilio Telephony Configuration
| Variable | Description |
|---|---|
| TWILIO_ACCOUNT_SID | Twilio account identifier |
| TWILIO_AUTH_TOKEN | Twilio authentication token |
| TWILIO_EDGE | Twilio edge location for optimal routing |
| TWILIO_REGION | Twilio region for service operations |
| FROM_PHONE_NUMBER | Outbound caller ID phone number |
Redis Configuration
| Variable | Description |
|---|---|
| REDISHOST | Redis server hostname for session storage |
| REDISPORT | Redis server port |
| REDISPASSWORD | Redis authentication password |
| REDISDB | Redis database number |
Conversation Configuration
| Variable | Description |
|---|---|
| ENABLE_FILLERS | Enable/disable filler audio during processing delays |
| FILLER_AUDIO_PATH | Path to filler audio files |
Caching Configuration
| Variable | Description |
|---|---|
| LANGCHAIN_CACHE | LangChain caching strategy for improved performance |
Logging Configuration
| Variable | Description |
|---|---|
| LOG_LEVEL | Application logging verbosity level |
Telemetry Configuration
| Variable | Description |
|---|---|
| STUDIOTELEMETRY_COLLECTOR_ENDPOINT | OpenTelemetry collector endpoint |
| STUDIOTELEMETRY_COLLECTOR_AUTH_TOKEN | Authentication token for telemetry |
| STUDIOTELEMETRY_APP_NAME | Application name for telemetry identification |
Conversation Schema Configuration
| Variable | Description |
|---|---|
| TRANSCRIPT_SUMMARY_SCHEMA | JSON schema defining conversation summary structure |
Resource Requirements
- CPU: 250m (requests) / 500m (limits)
- Memory: 512Mi (requests) / 3Gi (limits)
Autoscaling
- Min Replicas: 1
- Max Replicas: 1
- Target CPU Utilization: 70%
- Target Memory Utilization: 80%
Node Placement
- Node Selector:
node-pool: app-node - Tolerations:
workload=app:NoSchedule
Health Check: /
Dependencies: Redis, PostgreSQL, Azure OpenAI, Azure Speech, ElevenLabs, Twilio, SQS
Voice Backend Service
Voice call management and scheduling backend service that handles voice call orchestration, scheduling, and integration with telephony services.
AWS Integration
| Variable | Description |
|---|---|
| AWS_SQS_QUEUE_URL | SQS queue URL for voice call processing |
| AWS_REGION_NAME | AWS region for all AWS service operations |
Database Configuration
| Variable | Description |
|---|---|
| DATABASE_URL | PostgreSQL connection string for call data persistence |
ElevenLabs Voice Configuration
| Variable | Description |
|---|---|
| ELEVENLABS_API_KEY | ElevenLabs API key for voice synthesis |
| ELEVENLABS_EXPERIMENTAL_STREAMING | Enable experimental streaming features |
| ELEVENLABS_EXPERIMENTAL_WEBSOCKET | Enable WebSocket-based streaming |
| ELEVENLABS_MODEL_ID | ElevenLabs voice model identifier |
| ELEVENLABS_OPTIMIZE_STREAMING_LATENCY | Latency optimization level |
| ELEVENLABS_VOICE_ID | Specific voice ID for synthesis |
Twilio Configuration
| Variable | Description |
|---|---|
| TWILIO_ACCOUNT_SID | Twilio account identifier |
| TWILIO_AUTH_TOKEN | Twilio authentication token |
| TWILIO_EDGE | Twilio edge location for routing |
| TWILIO_REGION | Twilio region for operations |
| FROM_PHONE_NUMBER | Outbound caller ID phone number |
Azure OpenAI Configuration
| Variable | Description |
|---|---|
| AZURE_API_KEY | Azure OpenAI API key |
| AZURE_ENDPOINT | Azure OpenAI endpoint |
Analytics Integration
| Variable | Description |
|---|---|
| HULAHO_API_BASE_URL | Analytics API endpoint |
| HULAHO_ADMIN_USERNAME | Analytics platform admin username |
| HULAHO_ADMIN_PASSWORD | Analytics platform admin password |
Scheduling Configuration
| Variable | Description |
|---|---|
| SCHEDULE_BUCKET_NAME | S3 bucket for call scheduling data |
| SCHEDULER_LAMBDA_DURATION_IN_MILLIS | Lambda function timeout in milliseconds |
Service Configuration
| Variable | Description |
|---|---|
| ENABLE_CONTACT_POLICY | Enable/disable contact policy enforcement |
| LOG_LEVEL | Application logging verbosity |
| QUEUE_SERVICE | Message queue service type |
Resource Requirements
- CPU: 1000m (requests) / 1290m (limits)
- Memory: 1Gi (requests) / 2Gi (limits)
Node Placement
- Node Selector:
node-pool: app-node - Tolerations:
workload=app:NoSchedule
Health Check: /health
Dependencies: SQS, S3, ElevenLabs, Twilio, PostgreSQL, Azure OpenAI
Voice Scheduler Service
Automated voice call scheduling and management service that handles call timing, contact policies, and queue management.
Application Configuration
| Variable | Description |
|---|---|
| APPLICATION_NAME | Service identifier for logging and monitoring |
Scheduling Configuration
| Variable | Description |
|---|---|
| ALLOWED_WEEKDAYS | Comma-separated list of allowed days for scheduling calls (0=Monday) |
| TIMEZONE | Timezone for scheduling operations |
| SUCCESSFUL_CALLS_ALLOWED | Maximum successful calls per contact |
| RETRIES_ALLOWED | Maximum retry attempts per call |
Contact Policy Configuration
| Variable | Description |
|---|---|
| ENABLE_CONTACT_POLICY | Enable/disable contact policy enforcement |
| CONTACT_POLICY_ENABLED | Global contact policy toggle |
| GLOBAL_CONTACT_POLICY_START_TIME_IN_24_HOURS_FORMAT | Daily contact window start time |
| GLOBAL_CONTACT_POLICY_END_TIME_IN_24_HOURS_FORMAT | Daily contact window end time |
Database Configuration
| Variable | Description |
|---|---|
| DATABASE_URL | PostgreSQL connection string for scheduling data |
Azure Service Bus Configuration
| Variable | Description |
|---|---|
| AZURE_BUS_CONNECTION_STRING | Azure Service Bus connection string |
| AZURE_BUS_QUEUE_NAME | Azure Service Bus queue name |
AWS SQS Configuration
| Variable | Description |
|---|---|
| AWS_SQS_QUEUE_URL | SQS queue URL for voice call processing |
| AWS_REGION_NAME | AWS region for SQS operations |
Service Integration
| Variable | Description |
|---|---|
| VOICE_SERVICE_BASE_URL | Voice agent service internal URL |
| QUEUE_SERVICE | Primary queue service type (azure/aws) |
Logging Configuration
| Variable | Description |
|---|---|
| LOG_LEVEL | Application logging verbosity level |
Resource Requirements
- CPU: 1000m (requests) / 1290m (limits)
- Memory: 1Gi (requests) / 2Gi (limits)
Node Placement
- Node Selector:
node-pool: app-node - Tolerations:
workload=app:NoSchedule
Health Check: /health
Dependencies: Azure Service Bus, SQS, PostgreSQL, Voice Agent Service
KPI Events Polling Service
Analytics and metrics collection service that processes platform events and generates insights using AI models.
Application Configuration
| Variable | Description |
|---|---|
| APPLICATION_NAME | Service identifier |
| APPLICATION_VERSION | Application version for tracking |
| RUNTIME_MODE | Service operation mode |
| PORT | Application server port |
Database Configuration
| Variable | Description |
|---|---|
| DATABASE_URL | PostgreSQL connection string for event storage |
Queue Configuration
| Variable | Description |
|---|---|
| QUEUE_SERVICE | Queue service provider |
| KPI_EVENTS_SQS_QUEUE_NAME | SQS queue name for KPI events |
| KPI_EVENTS_SQS_REGION_NAME | AWS region for KPI events queue |
| AWS_SQS_QUEUE_NAME | AWS SQS queue name |
| AWS_REGION_NAME | AWS region for operations |
AWS Bedrock Model Configuration
| Variable | Description |
|---|---|
| AWS_BEDROCK_MODEL_NAME | Bedrock model identifier for event analysis |
| AWS_BEDROCK_MODEL_MAX_TOKENS | Maximum tokens per request |
| AWS_BEDROCK_MODEL_TEMPERATURE | Model temperature for deterministic responses |
| AWS_BEDROCK_MODEL_TOP_K | Top-k sampling parameter |
| AWS_BEDROCK_MODEL_TOP_P | Top-p sampling parameter |
Telemetry Configuration
| Variable | Description |
|---|---|
| STUDIOOPS_OTEL_ENDPOINT | OpenTelemetry endpoint for metrics |
Logging Configuration
| Variable | Description |
|---|---|
| LOG_LEVEL | Application logging verbosity level |
Resource Requirements
- CPU: 200m (requests) / 1290m (limits)
- Memory: 512Mi (requests) / 2Gi (limits)
Node Placement
- Node Selector:
node-pool: app-node - Tolerations:
workload=app:NoSchedule
Health Check: /api/v1/health
Dependencies: SQS, AWS Bedrock, PostgreSQL, StudioOps
EKS Jobs Managing Service
Kubernetes job orchestration and management service that handles batch processing and job lifecycle management.
Application Configuration
| Variable | Description |
|---|---|
| APPLICATION_NAME | Service identifier for logging and monitoring |
| PORT | Application server port |
Resource Requirements: Default allocation
Node Placement: Default (no specific node selector configured)
Health Check: /api/v1/health
Dependencies: Kubernetes API, RBAC permissions for job management
Voice Redis Service
In-memory data store for voice services session management and caching.
Redis Configuration
| Configuration | Description |
|---|---|
| Architecture | Deployment architecture (standalone/cluster) |
| Authentication | Password authentication enabled |
| Password | Redis authentication password |
| Persistence | Data persistence configuration (disabled for performance) |
Resource Requirements
- CPU: 1200m (requests) / 1290m (limits)
- Memory: 1Gi (requests) / 2Gi (limits)
Node Placement
- Node Selector:
node-pool: app-node - Tolerations:
workload=app:NoSchedule
Health Check: Redis ping command
Dependencies: None (standalone service)
Langfuse (StudioOps) Service
LLM observability, analytics, and evaluation platform providing comprehensive monitoring and analysis of AI model performance.
Components
- Web Interface: Dashboard and API endpoints
- Worker: Background processing for analytics
- ClickHouse: Time-series database for metrics storage
- PostgreSQL: Metadata and configuration storage
Core Configuration
| Variable | Description |
|---|---|
| LANGFUSE_KEY | Langfuse API key for authentication |
| NEXTAUTH_URL | NextAuth authentication URL |
| NEXT_PUBLIC_LANGFUSE_CLOUD_REGION | Cloud region (empty for self-hosted) |
| NODE_OPTIONS | Node.js memory optimization flags |
Database Configuration
| Variable | Description |
|---|---|
| DATABASE_URL | PostgreSQL connection string |
| DIRECT_URL | Direct database connection URL |
ClickHouse Configuration
| Variable | Description |
|---|---|
| CLICKHOUSE_MIGRATION_SSL | SSL for ClickHouse migrations |
| CLICKHOUSE_CLUSTER_ENABLED | Cluster deployment mode |
| LANGFUSE_AUTO_CLICKHOUSE_MIGRATION_DISABLED | Automatic migration toggle |
| LANGFUSE_CLICKHOUSE_ENABLED | ClickHouse integration toggle |
| CLICKHOUSE_DB | ClickHouse database name |
Feature Flags
| Variable | Description |
|---|---|
| LANGFUSE_ENABLE_EXPERIMENTAL_FEATURES | Enable experimental features |
| LANGFUSE_ENABLE_BACKGROUND_MIGRATIONS | Enable background database migrations |
AWS S3 Dataset Configuration
| Variable | Description |
|---|---|
| LANGFUSE_S3_DATASET_UPLOAD_BUCKET | S3 bucket for dataset uploads |
| LANGFUSE_S3_DATASET_UPLOAD_PREFIX | S3 prefix for dataset files |
| LANGFUSE_S3_DATASET_UPLOAD_REGION | AWS region for S3 operations |
| LANGFUSE_S3_DATASET_UPLOAD_ENDPOINT | S3 endpoint URL |
| LANGFUSE_S3_DATASET_UPLOAD_FORCE_PATH_STYLE | Force path-style S3 URLs |
| AWS_REGION | AWS region for all operations |
Bedrock Evaluation Configuration
| Variable | Description |
|---|---|
| EKS_JOB_MANAGING_SERVICE_TRIGGER_URL | EKS job trigger endpoint |
| EKS_TRANSFORM_JOB_NAME | Transformation job name |
| BEDROCK_EVALATION_DATA_TRANSFORMATION_ECR_IMAGE_REPO_URI | Container image for evaluation |
| CHATTEROPS_BASE_URL | ChatterOps integration URL |
| BEDROCK_EVALUATION_DATA_TRANSFORMATION_S3_BUCKET_NAME | S3 bucket for evaluation data |
| DATA_TRANSFORMATION_EKS_CLUSTER_AWS_REGION_NAME | AWS region for EKS operations |
| BEDROCK_EVALUATION_DATA_TRANSFORMATION_JOB_CONTAINER_TYPE | Container type for evaluation jobs |
| BEDROCK_EVALUATION_DATA_TRANSFORMATION_JOB_EXECUTION_COMMAND | Job execution command |
| BEDROCK_EVALUATION_EKS_JOB_NAMESPACE | Kubernetes namespace for evaluation jobs |
| STUDIOOPS_DATABASE_URL | StudioOps database connection |
AWS Bedrock Evaluation Execution
| Variable | Description |
|---|---|
| AWS_BEDROCK_ROLE_ARN | IAM role for Bedrock evaluations |
| INHOUSE_EVALUATION_ECR_IMAGE_REPO_URI | In-house evaluation service image |
| INHOUSE_EVALUATION_EKS_JOB_NAMESPACE | Namespace for in-house evaluation jobs |
| INHOUSE_EVALUATION_JOB_NAME | In-house evaluation job name |
Resource Requirements: Default allocation with ClickHouse requiring dedicated resources
Node Placement
- Node Selector:
node-pool: studiops-node - Tolerations:
workload=studiops:NoSchedule
Health Checks
- Web:
/api/public/health,/api/public/ready - Worker: Process-based health monitoring
Dependencies: PostgreSQL, ClickHouse, Redis, S3, AWS Bedrock, EKS Jobs Managing Service
Threads Service
Conversation thread management and persistence service that handles multi-turn conversations, thread state management, and conversation history storage.
Application Configuration
| Variable | Description |
|---|---|
| APPLICATION_NAME | Service identifier for logging and monitoring |
| APPLICATION_VERSION | Application version for tracking and compatibility |
| HOST | Application bind address for container networking |
| PORT | Application server port |
Database Configuration
| Variable | Description |
|---|---|
| DATABASE_URL | PostgreSQL connection string for thread persistence |
Service Integration
| Variable | Description |
|---|---|
| FLOW_SERVICE_BASE_URL | Agentic Flow service endpoint for workflow integration |
Logging Configuration
| Variable | Description |
|---|---|
| LOG_LEVEL | Application logging verbosity level |
Resource Requirements
- CPU: 1000m (requests) / 1290m (limits)
- Memory: 1Gi (requests) / 2Gi (limits)
Node Placement
- Node Selector:
node-pool: app-node - Tolerations:
workload=app:NoSchedule
Health Check: /api/v1/health
Dependencies: PostgreSQL, Agentic Flow Service
Hulaho Service
Business intelligence and analytics dashboard platform built on Apache Superset, providing comprehensive data visualization and reporting capabilities.
Components
- Superset Node: Main web application and API server
- Celery Worker: Background task processing for reports
- Celery Beat: Scheduled job execution (optional)
- Celery Flower: Celery monitoring UI (optional)
- WebSocket Server: Real-time updates support (optional)
Application Configuration
| Variable | Description |
|---|---|
| APP_NAME | Application display name |
| WEB_PROXY_URL | Base URL for the application |
| FAVICONS | Custom favicon configuration (JSON array) |
| APP_ICON | Application logo path |
| LOGOUT_REDIRECT_URL | Post-logout redirect destination |
Database Configuration
| Variable | Description |
|---|---|
| DB_USER | PostgreSQL username |
| DB_PASS | PostgreSQL password |
| DB_HOST | PostgreSQL host |
| DB_PORT | PostgreSQL port |
| DB_NAME | PostgreSQL database name |
Redis Configuration
| Variable | Description |
|---|---|
| REDIS_HOST | Redis server hostname for caching and sessions |
| REDIS_PORT | Redis server port |
| REDIS_PASSWORD | Redis authentication password |
Authentication Configuration
| Variable | Description |
|---|---|
| AUTH_TYPE | Authentication method (e.g., AUTH_OAUTH) |
| AUTH_USER_REGISTRATION | Allow automatic user registration |
| AUTH_USER_REGISTRATION_ROLE | Default role for new users |
| OAUTH_USER_PASSWORD | OAuth user default password |
Azure AD OAuth Configuration
| Variable | Description |
|---|---|
| OAUTH_PROVIDERS | OAuth provider configuration (JSON object with Azure AD details) |
Security Configuration
| Variable | Description |
|---|---|
| TALISMAN_ENABLED | Talisman security headers toggle |
| ENABLE_CORS | Cross-Origin Resource Sharing toggle |
| HTTP_HEADERS | Custom HTTP headers (JSON object) |
| WTF_CSRF_ENABLED | CSRF protection toggle |
| SESSION_COOKIE_SAMESITE | Cookie SameSite policy |
| SESSION_COOKIE_SECURE | Require HTTPS for cookies |
| ENABLE_PROXY_FIX | Proxy header processing toggle |
Feature Flags
| Variable | Description |
|---|---|
| THUMBNAILS | Dashboard thumbnails toggle |
| EMBEDDED_SUPERSET | Embedded dashboard capabilities toggle |
Thumbnail Configuration
| Variable | Description |
|---|---|
| THUMBNAIL_CACHE_CONFIG | Redis-based thumbnail caching configuration |
| WEBDRIVER_BASEURL | Base URL for screenshot generation |
| SCREENSHOT_SELENIUM_HEADSTART | Selenium startup delay in seconds |
Resource Requirements
- Superset Node: CPU 1000m, Memory 4096Mi
- Celery Worker: CPU 1000m, Memory 4096Mi
- Init Job: CPU 512m-1000m, Memory 1024Mi-4096Mi
Node Placement
- Node Selector:
node-pool: app-node - Tolerations:
workload=app:NoSchedule
Health Check: /health
Dependencies: PostgreSQL, Redis, Azure AD OAuth
Initialization
- Database Migration: Automatic database schema upgrades
- Admin User Creation: Default admin user with configurable credentials
- Role Initialization: Automatic role and permission setup
Best Practices
Security
- Use IRSA (IAM Roles for Service Accounts) for AWS service access
- Store sensitive data in Kubernetes secrets or HashiCorp Vault
- Enable TLS for all external communications
- Implement network policies for service isolation
Monitoring
- Configure health checks for all services
- Set up resource limits and requests
- Monitor application logs through CloudWatch
- Use StudioOps (Langfuse) for LLM observability
Scaling
- Configure HPA for services with variable load
- Use appropriate node selectors and tolerations
- Monitor resource utilization and adjust limits
- Consider cluster autoscaling for dynamic workloads
Maintenance
- Regular backup of PostgreSQL databases
- Monitor S3 storage costs and lifecycle policies
- Keep container images updated with security patches
- Test rollback procedures in staging environment
Troubleshooting
Common Issues
Pod Scheduling Issues
kubectl describe pod <pod-name> -n <namespace>
# Check node selectors, tolerations, and resource availability
Service Discovery Problems
kubectl get endpoints -n <namespace>
# Verify service endpoints are populated
Ingress Configuration
kubectl describe ingress -n <namespace>
# Check ALB controller logs and certificate status
Database Connectivity
kubectl exec -it <pod-name> -n <namespace> -- nc -zv <db-host> <db-port>
# Test database connectivity from pods
Log Analysis
# Application logs
kubectl logs -f deployment/<service-name> -n <namespace>

# Previous container logs (for crash analysis)
kubectl logs deployment/<service-name> -n <namespace> --previous

# Multiple container logs
kubectl logs -f deployment/<service-name> -c <container-name> -n <namespace>